
Hey, I'm Pablo (or Pablin, if you're one of my people)
I'm currently trying to survive a master's in Computer Science applied to Artificial Intelligence, basically a huge nerd into Machine Learning, AI, quantized models, and stuff running on my own infra, mostly SLMs (screw big tech... nah, kidding, obviously I used uncle Claude and cousin Gemini to build this blog lmaooo). This blog is where I document what I'm studying (me and my models, local or not), metaphors and all, without ever dodging the real technical terms. The whole point here is getting you to walk away with something you can actually apply to your own project or your own studies, same thing I'm trying to do, honestly.
Latest posts
See all- From the First wx+b to Here: Closing the Course
2026-09-09
20 posts later, the specialization's first course (Supervised Regression and Classification) is done. A look back at what actually stuck, the certificate, and what this playlist taught me about reusing the same tool instead of learning a new one every chapter.
- Gradient Descent Didn't Need to Learn Anything New
2026-09-08
Week 3, Lab 6: after sigmoid, decision boundary, logistic loss and cost, only one piece is left to actually train something. Good news: that piece has existed since Week 1, the same gradient descent loop, just walking down a different hill.
- What Took Six Labs, Scikit-Learn Does in Three Lines
2026-09-08
Week 3, Lab 7: sigmoid, decision boundary, loss, cost and gradient descent, all hand-written over the last six labs, collapse into import, fit, predict. And the comparison with real sklearn drops a spoiler for the course's next topic.
Timeline
See all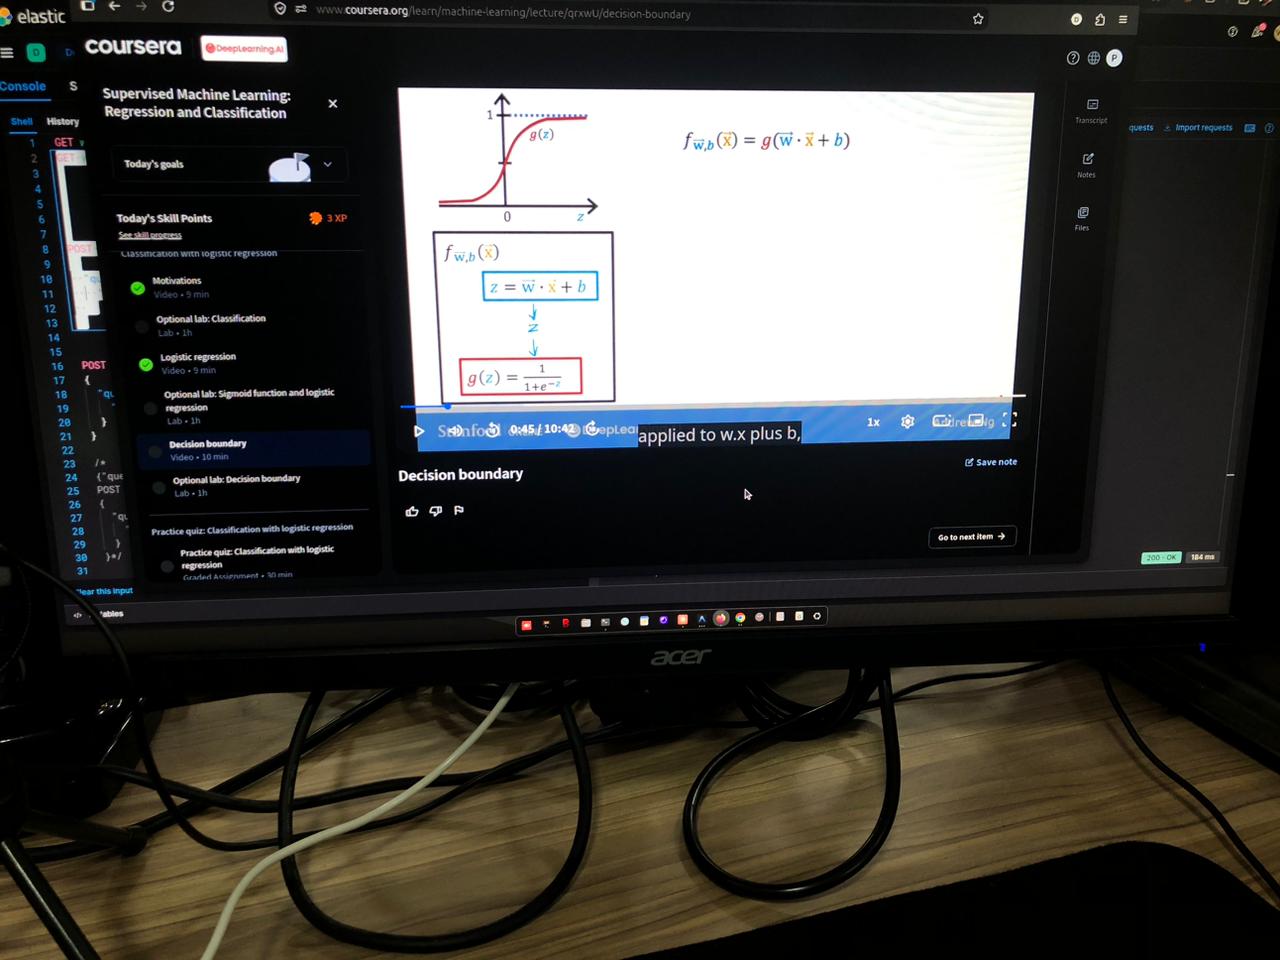
 Getting shaken up by Go
2026-08-19
Playlists
- Machine Learning Specialization (Andrew Ng)
My step-by-step notes going through Andrew Ng's Machine Learning Specialization (DeepLearning.AI / Stanford), course by course, lab by lab.
- Pattern Recognition
My notes from my Pattern Recognition course, lecture by lecture, with Bishop's book as the theoretical backbone.
- Neural Networks
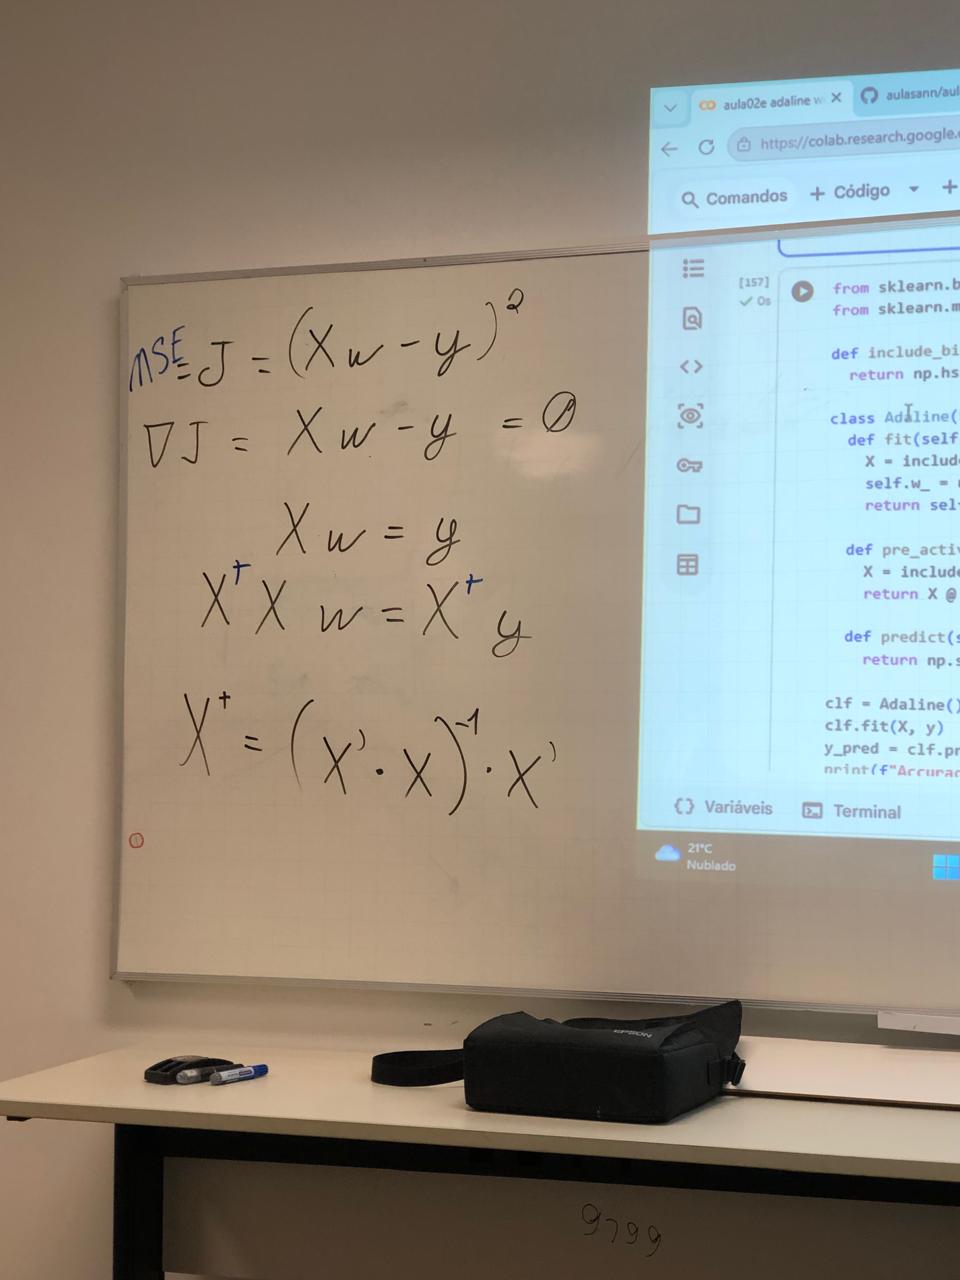
My notes from my Neural Networks course, lecture by lecture, with Aggarwal's book as the theoretical backbone. A living playlist, growing along with the course.
- Papers
A diagonal read of articles and surveys I found cool, with no pretense of turning into a lecture. Simple code, a chart to give you a view, and the same conversation as always with you.
- Small Language Models
Chapter by chapter through "How to Build and Fine-Tune a Small Language Model", by J. Paul Liu. Why train your own model instead of outsourcing everything to an API, and how to build a GPT from scratch until it writes like a 19th-century Brazilian novelist.